- Home Page /
- Books /
- Computers & Technology /
- Computer Science /
- AI & Machine Learning /
- Intelligence & Semantics /
- Reinforcement Learning from Human Feedback: L...


Item #:
248983336
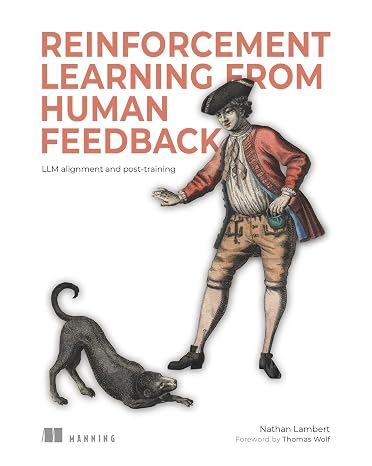
Reinforcement Learning from Human Feedback: LLM alignment and post-training
89% of respondents would recommend this to a friend
Item #:
248983336
STD 1954695
Price Details
Excluding Shipping & Custom charges ( Shipping and custom charges will be calculated on checkout )
*All items will import from US
0 ratings
Write a review
In stock
 Imported from USA store
QTY:
Order now and get it around Thursday, October 15
Secured transaction
Ubuy works hard to protect your security and privacy. Our advanced payment security system ensures confidentiality by encrypting your information during transmission using AES (Advanced Encryption Standards) and SSL (Secure Socket Layer) protocols. Your payment details are 100% secure as we do not share your payment details with third party sellers.
Our Top Logistics Partners


Reinforcement Learning from Human Feedback helps you understand one of the most important techniques behind modern LLM alignment and post-training.

Fast
Shipping

Free
Return*

Secure Packaging

100% Original Products

PCI DSS Compliance

ISO 27001 Certified



Note: Step Down Voltage Transformer required for using electronics products of US store (110-120). Recommended power converters Buy Now.


What Stands Out
Human-Centric Training
Utilizes human feedback to fine-tune models, ensuring that AI aligns closely with user values and preferences, enhancing satisfaction and real-world applicability.
Post-Training Optimization
Offers advanced techniques for model alignment after initial training, ensuring continual improvement and adaptation, which outperforms static models in dynamic environments.
Enhanced Safety Measures
Integrates rigorous safety protocols to minimize risks associated with AI decision-making, providing users and developers with greater confidence in AI deployment.
Product Details
- Get the eBook free when you register your print book at Manning.A masterful synthesis of the field’s intellectual roots and its practical tools.”—Saurabh Sawant, MicrosoftReinforcement Learning from Human Feedback: LLM alignment and post-training helps you understand how modern AI models can be adapted to better match the needs and expectations of their users. Rather than surveying the vast field of reinforcement learning, elite AI researcher Nathan Lambert concentrates exclusively on RLHF and its immediate importance to post-training generative AI models.This compact book gets right to the point. Early chapters establish the training overview, explain instruction fine-tuning, and build reliable reward models. The middle chapters transition into the heart of alignment, exploring core policy gradient algorithms, Direct Preference Optimization (DPO), and inference-time scaling. Later chapters tackle the messy reality of data, guiding you through preference data collection, synthetic data generation, and the nuances of function calling.As you go, you will see how these post-training methods actually work, including their unique compute costs and latency trade-offs. You will explore common failure modes, such as qualitative over-optimization, reward hacking, and the unreliability of external evaluation comparisons. Difficult concepts like KL regularization, proximal policy optimization, and generative reward modeling are clarified with hands-on experiments.Reinforcement Learning from Human Feedback avoids irrelevant academic details in favor of immediate, practical value. Everything author Nathan Lambert includes appears because a modern RLHF project requires it. He skillfully explains complex post-training pipelines by making every detail concrete, connecting isolated abstractions directly to the goal of making models safer, smarter, and perfectly tuned to a desired style.The book’s seventeen short chapters lay out the core material, while supplements like vocabulary definitions, compute cost management, evaluation variance, and training performance tracking appear in handy appendixes. The result is a logically flowing book that remains highly navigable and technically deep without getting bogged down in unnecessary theory.The book covers• Core RLHF implementations and Direct Alignment Algorithms• Building robust preference and synthetic data pipelines• Evaluating models and crafting specific AI personasAbout the readerFor established engineers, AI scientists, and students trying to get a practical foothold in AI model alignment.About the authorDr. Nathan Lambert is a leading AI researcher known for leading post-training at the Allen Institute for AI. With previous experience at HuggingFace, DeepMind, and Meta, he is a passionate advocate for open models. His work focuses on increasing access to, and the understanding of, AI technology—empowering readers to contribute to the advancement of AI outside closed corporate labs.Table of ContentsPart 11 Introduction2 A tiny history of RLHF3 Training overviewPart 24 Instruction fine-tuning5 Reward modeling6 Reinforcement learning7 Reasoning and inference-time scaling8 Direct-alignment algorithms9 Rejection samplingPart 310 The nature of preferences11 Preference data12 Synthetic dataPart 413 Tool use and function calling14 Over-optimization15 Regularization16 Evaluation17 Crafting model character and productsA DefinitionsB Beyond “just style”C Practical Issues
| Publisher | Manning Publications |
| Publication date | August 4, 2026 |
| Language | English |
| Print length | 312 pages |
| ISBN-10 | 1633434303 |
| ISBN-13 | 978-1633434301 |
| Item Weight | 8.5 ounces (240.98 grams) |
| Dimensions | 7.38 x 0.71 x 9.25 inches (18.7 x 1.8 x 23.5 cm) |
Product Description
Have any Query? Chat with us
Customer Questions & Answers
-
Question:
How to Shop Reinforcement Learning from Human Feedback: LLM Online From Ubuy?
Answer: It’s easy to shop Reinforcement Learning from Human Feedback: LLM online from Ubuy. You just have to search for the product, choose your shipping method while checking out and get it delivered to your location. -
Question:
Is Reinforcement Learning from Human Feedback: LLM Available to Shop Online in São Tomé and Príncipe?
Answer: Yes, at Ubuy São Tomé and Príncipe this product is available for you to shop at a reasonable price. The Reinforcement Learning from Human Feedback: LLM is not available locally but you can trust us with our express shipping services. -
Question:
How Long Does It Take to Get Product After Placing the Order?
Answer: The delivery time of your ordered product varies as per what you've ordered and the shipping method that you've chosen. The estimated delivery time is mentioned during the checkout process, so be carefree while shopping.
Intelligence & Semantics Editorial Review
No editorial reviews found
Customer Reviews & Ratings
14 customers ratings
-
5 Star
77%
-
4 Star
0%
-
3 Star
0%
-
2 Star
12%
-
1 Star
11%
Review this product
Share your thoughts with other customers
Customers also viewed these products

Product Price History
Important information
- Limitations : For products shipped internationally, please note that any manufacturer warranty may not be valid; manufacturer service options may not be available; product manuals, instructions, and safety warnings may not be in destination country languages; the products (and accompanying materials) may not be designed in accordance with destination country standards, specifications, and labeling requirements; and the products may not conform to destination country voltage and other electrical standards (requiring use of an adapter or converter if appropriate). The recipient is responsible for assuring that the product can be lawfully imported to the destination country. When ordering from Ubuy or its affiliates, the recipient is the importer of record and must comply with all laws and regulations of the destination country.
- Not all the products listed on Ubuy are for sale, as Ubuy is a global search engine. Products are subject to export/trade regulations.
STD 1954695
Order now and get it around Thursday, October 15
This item is not restrict in my country.(Please click on above link if this item is not restrict in your country, So our team will review and allow.)
QTY:
Secured transaction
PCI DSS compliant and ISO 27001:2022 certified, with encrypted payments and full buyer protection on every order.
Our Top Logistics Partners
Fastest cross-border delivery
Features & Benefits
- Gain insights into aligning AI models with human preferences.
- Practical guidance on reinforcement learning and its components.
- Focus on RLHF's impact on generative AI models.
- Hands-on experiments clarify complex concepts.
- Avoids unnecessary academic details for immediate application.
- Ideal for AI engineers, researchers, and technical leaders.
Ubuy Assurance
Experience worry-free shopping with 100% original products, PCI DSS-compliant payment security, ISO 27001-certified data protection, the fastest cross-border delivery, free returns *, and secure packaging on every order.